Hi there, I'm Aleksei Petrenko

Making computers do things at which, at the moment, people are better. (Rich and Knight, 1991)
I am a research scientist at Apple, currently working with Vladlen Koltun on RLVR post-training for interactive LLM agents.
I received my PhD in Computer Science in 2022 from the University of Southern California. I was part of the Robotic Embedded Systems Lab, advised by prof. Gaurav Sukhatme.
During my PhD I worked at NVIDIA on high-throughput simulation and RL for dexterous robots, and at Intel on massively parallel 3D rendering and high-throughput reinforcement learning. Before going to academia I spent 8 years in industry, working on software R&D, machine learning, algorithms, 3D graphics, computer vision, and virtual reality.
Research interests
I study computationally efficient methods for training in simulation using reinforcement learning, as well as problems of sim-to-real transfer. Recently I’ve been working on:
- Highly optimized systems for deep reinforcement learning, such as RL algorithms and simulators.
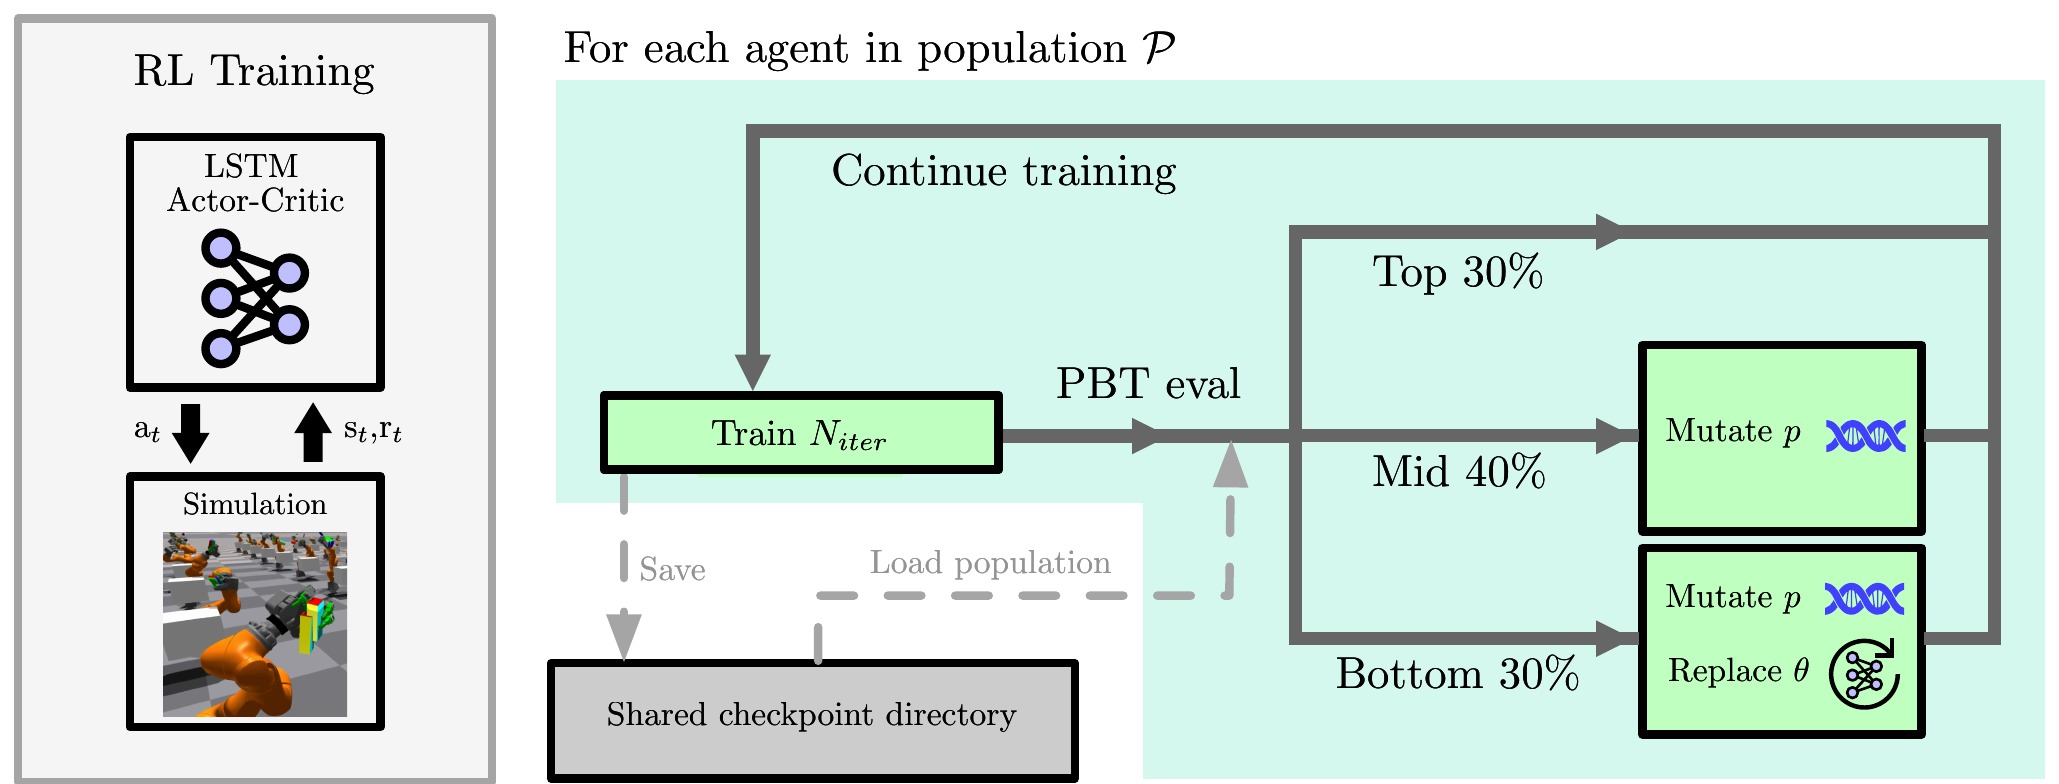
- Advanced training scenarios: population-based training and self-play.
- RL post-training with verifiable tasks for LLM agents.
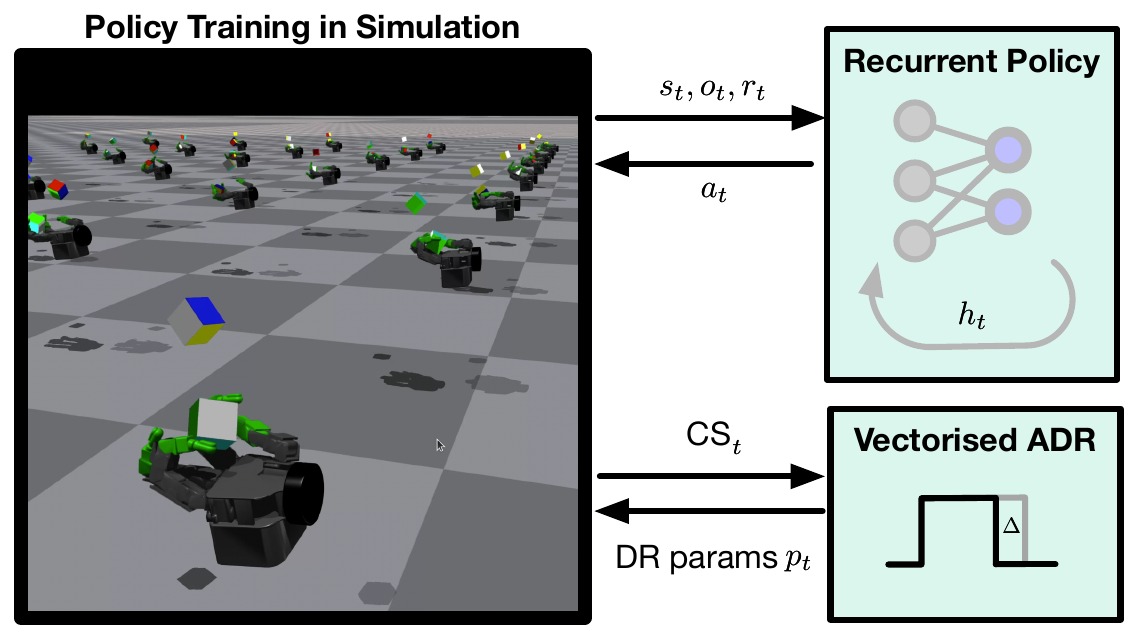
- Reinforcement learning in robotics: dexterous manipulation, autonomous driving, drones.
In the past I also worked on quality-diversity methods, exploration in RL, memory in embodied agents, and stochastic future prediction.
Selected publications All publications →
-
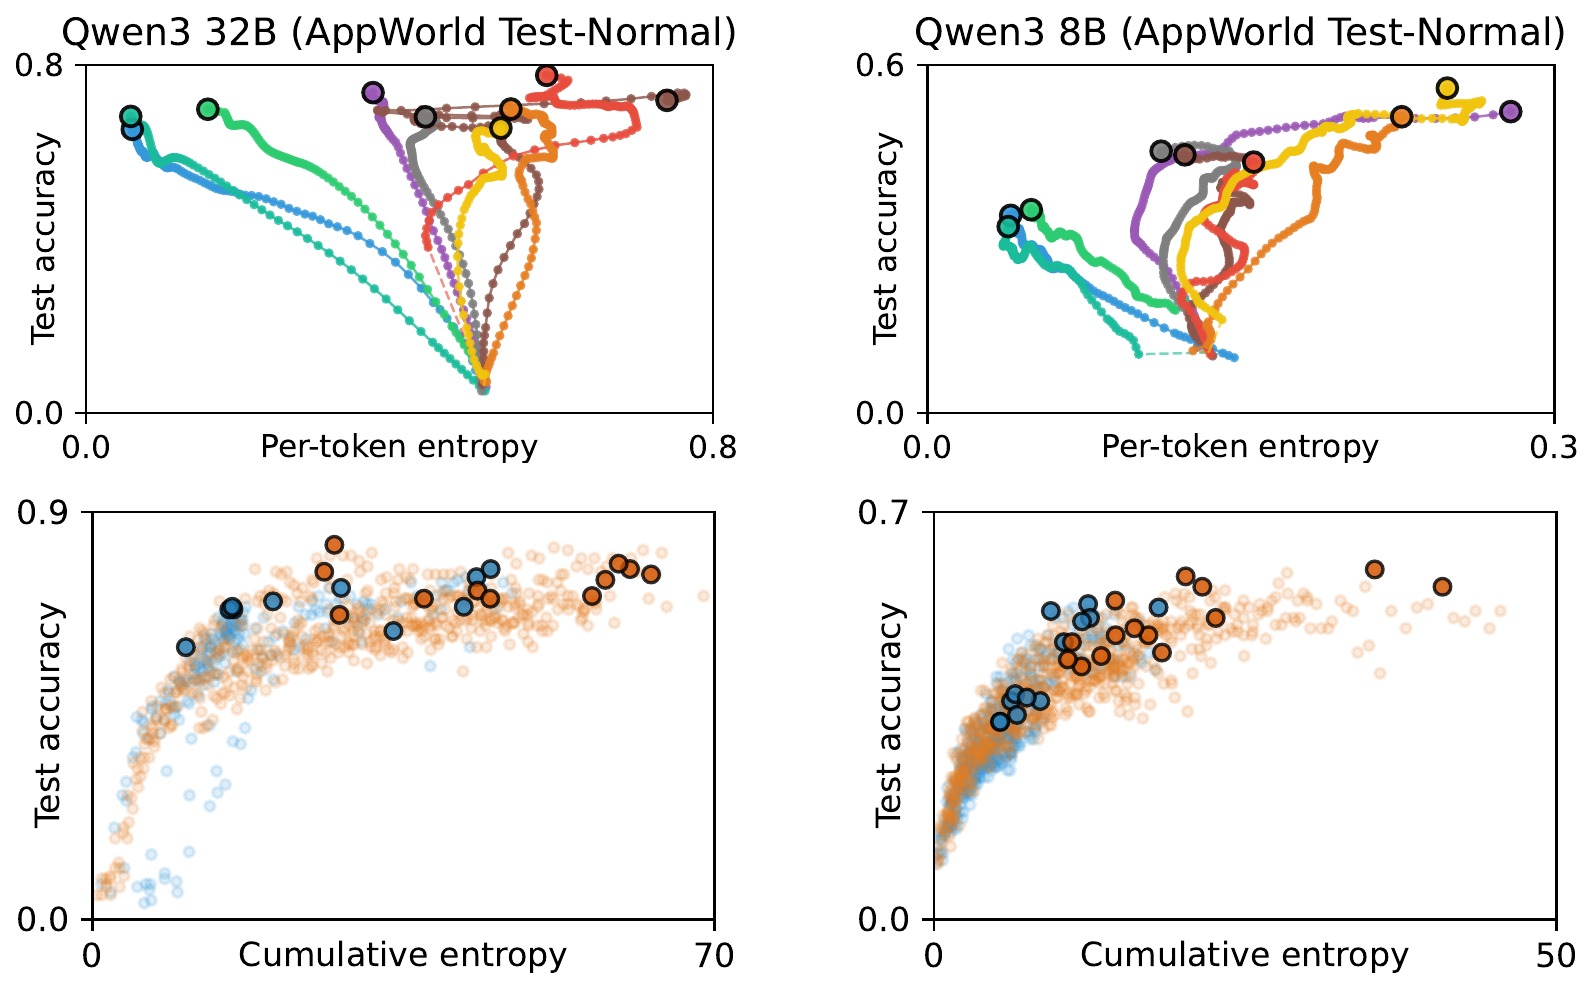 Entropy-Preserving Reinforcement Learning. In ICLR 2026.Policy gradient methods quietly collapse policy entropy during training; we introduce mechanisms that keep policies diverse, performant, and retrainable on new tasks.
-
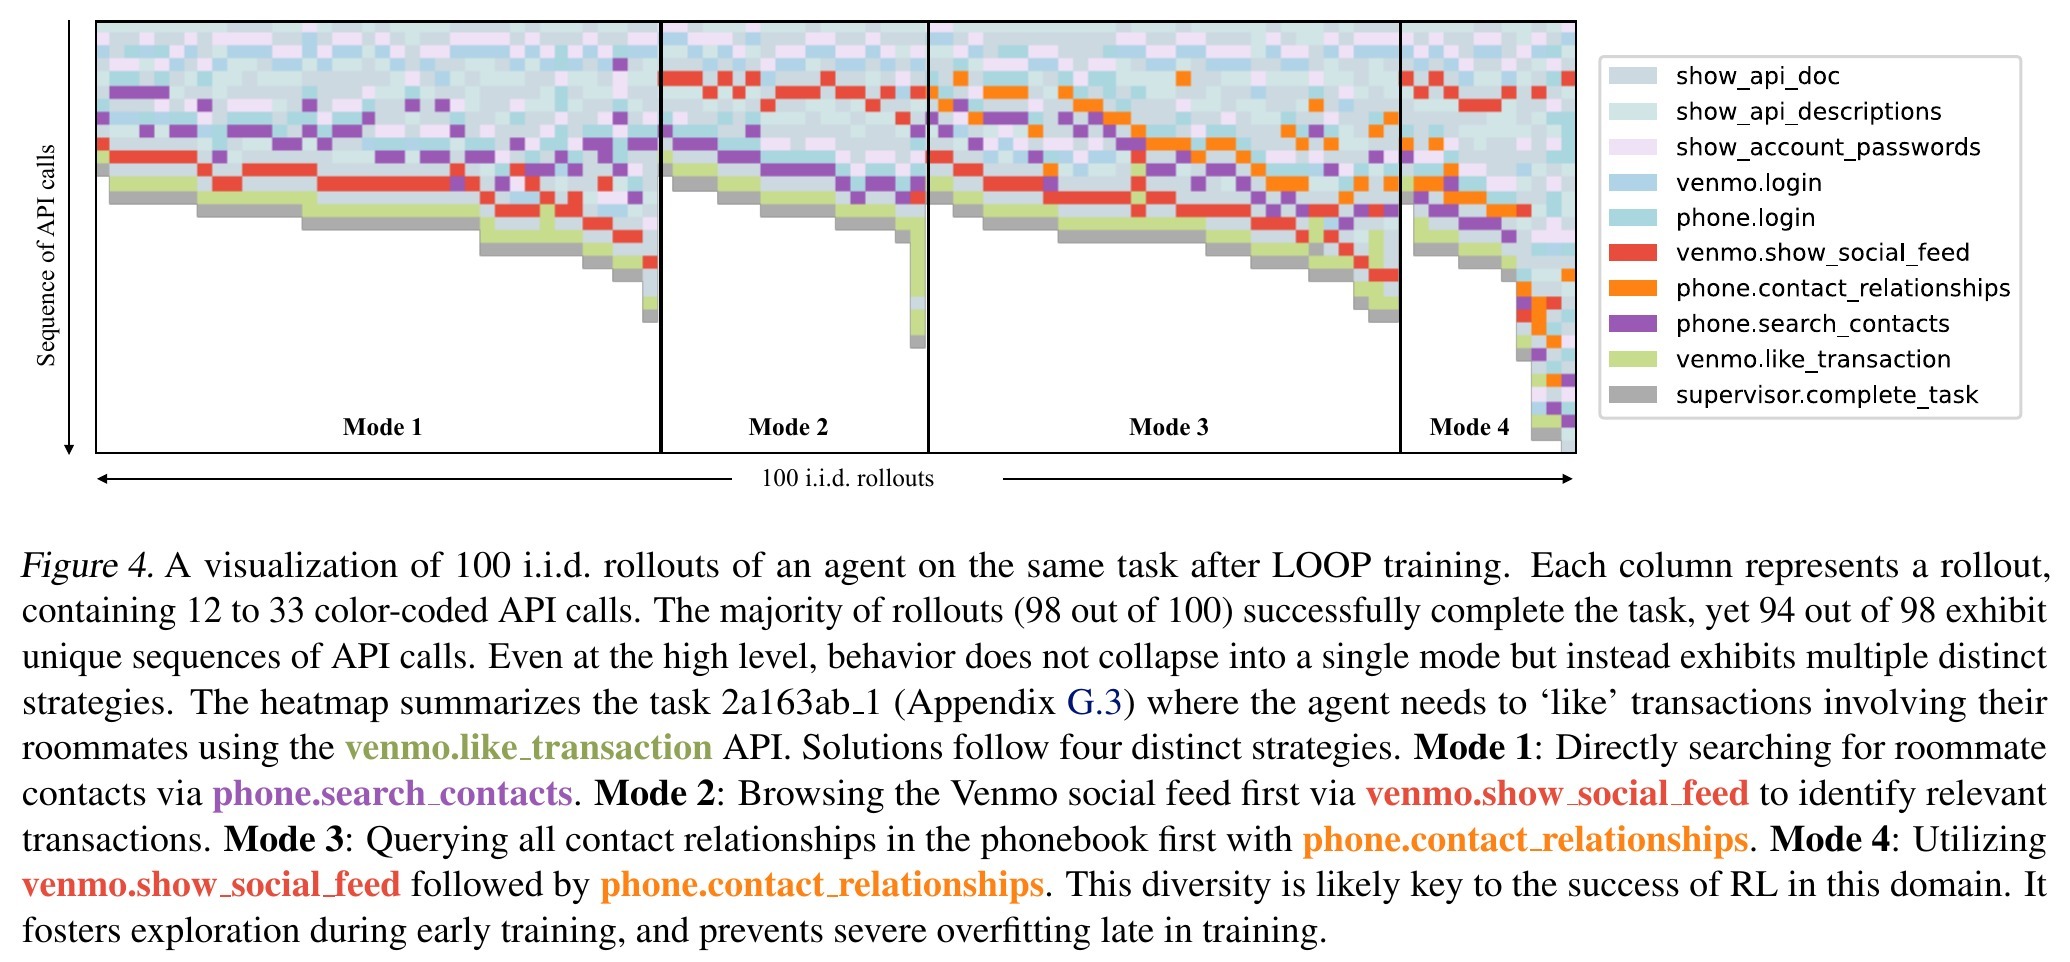 Reinforcement Learning for Long-Horizon Interactive LLM Agents. arXiv preprint, 2025.RL for long-horizon, multi-turn, tool-using LLM agents. A 32B Qwen2.5 LoRA fine-tune reached 71% on AppWorld, 9 points above OpenAI o1, after training on just 24 scenarios.
-
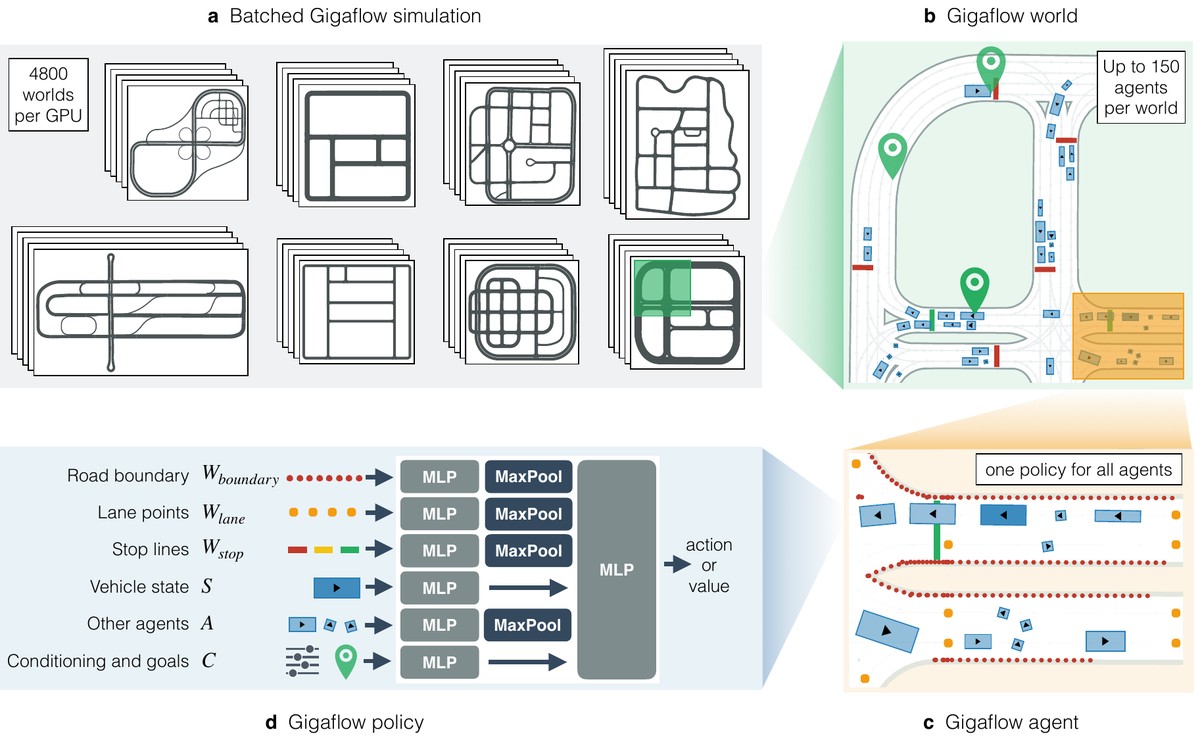 Robust Autonomy Emerges from Self-Play. In ICML 2025.Gigaflow, a batched driving simulator that trains on 42 years of driving experience per hour on a single 8-GPU node: robust and naturalistic driving emerges from 1.6 billion km of self-play, without ever seeing human data.
-
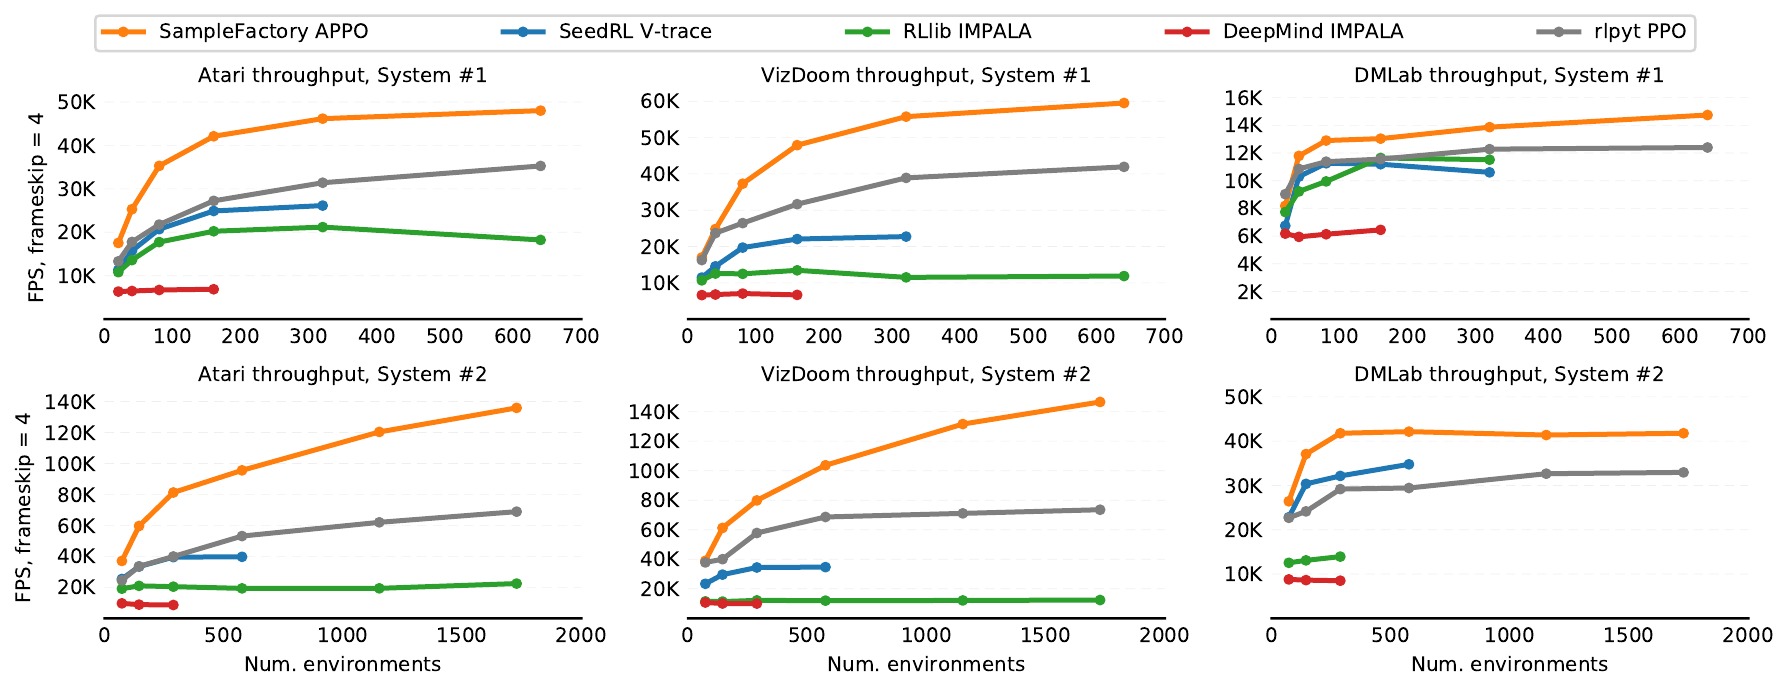 Sample Factory: Egocentric 3D Control from Pixels at 100000 FPS with Asynchronous Reinforcement Learning. In ICML 2020.Reinforcement learning framework with the highest single-machine training throughput at the time of publication, about 10x faster than traditional synchronous RL implementations. SOTA results in challenging VizDoom and DMLab environments.