Publications

* equal contribution · full list on Google Scholar

2026

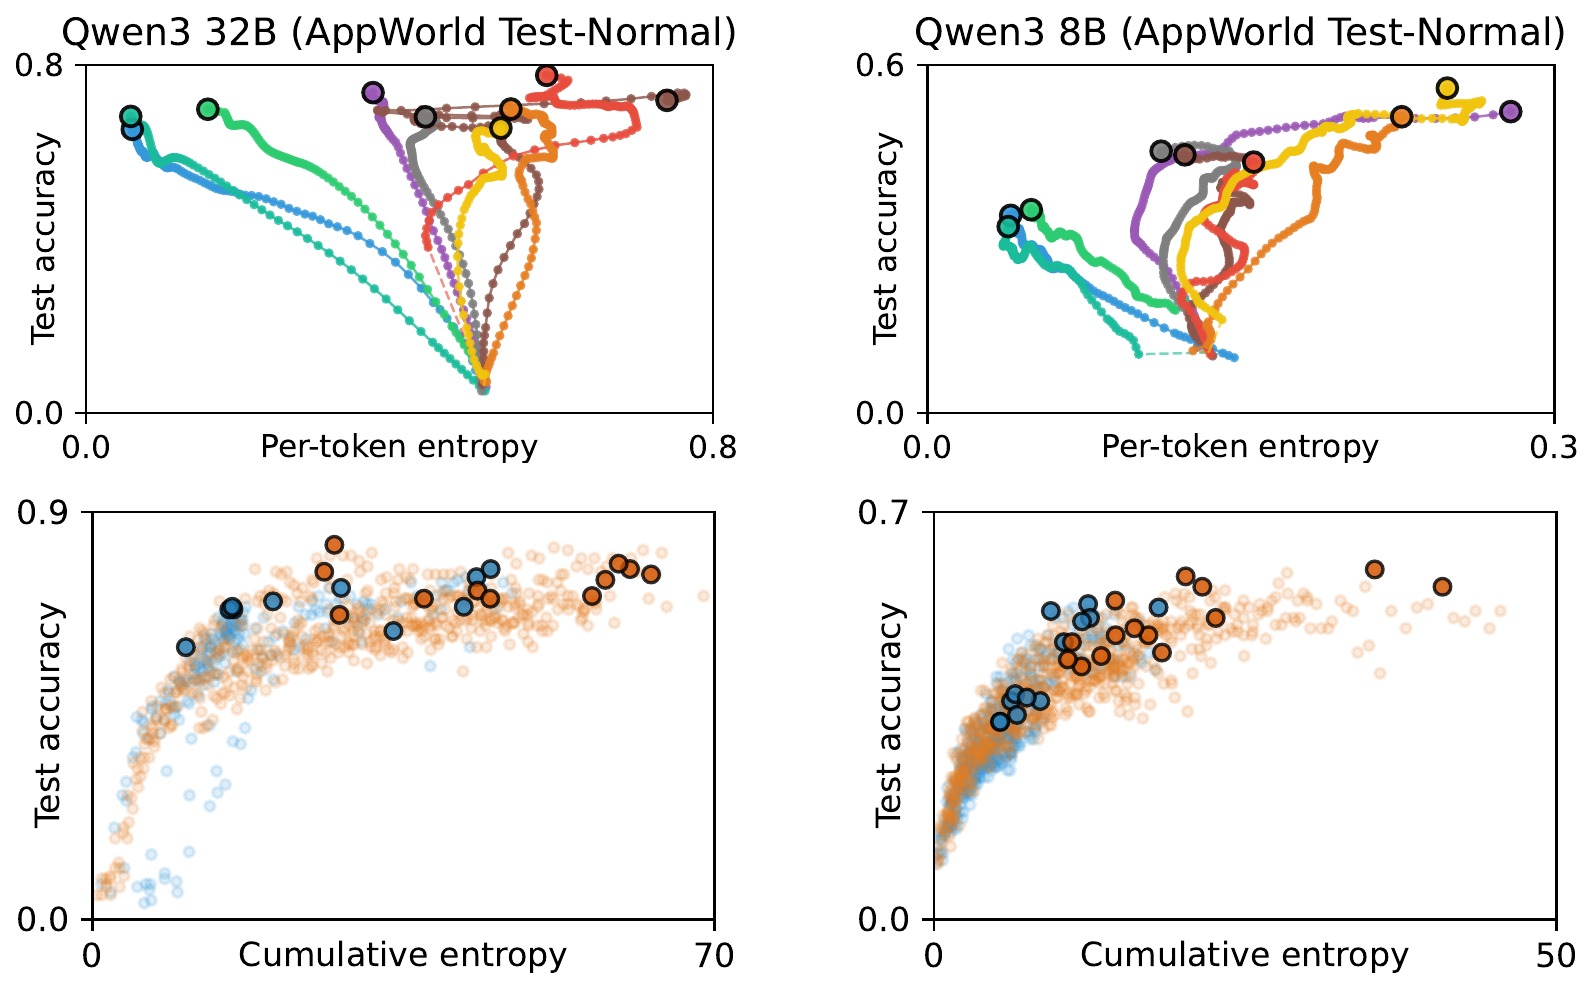
  1. Entropy-Preserving Reinforcement Learning
    Entropy-Preserving Reinforcement Learning. A Petrenko*, B Lipkin*, K Chen, E Wijmans, M Cusumano-Towner, R Giryes, P Krähenbühl. In ICLR 2026.
    Policy gradient methods quietly collapse policy entropy during training; we introduce mechanisms that keep policies diverse, performant, and retrainable on new tasks.

2025

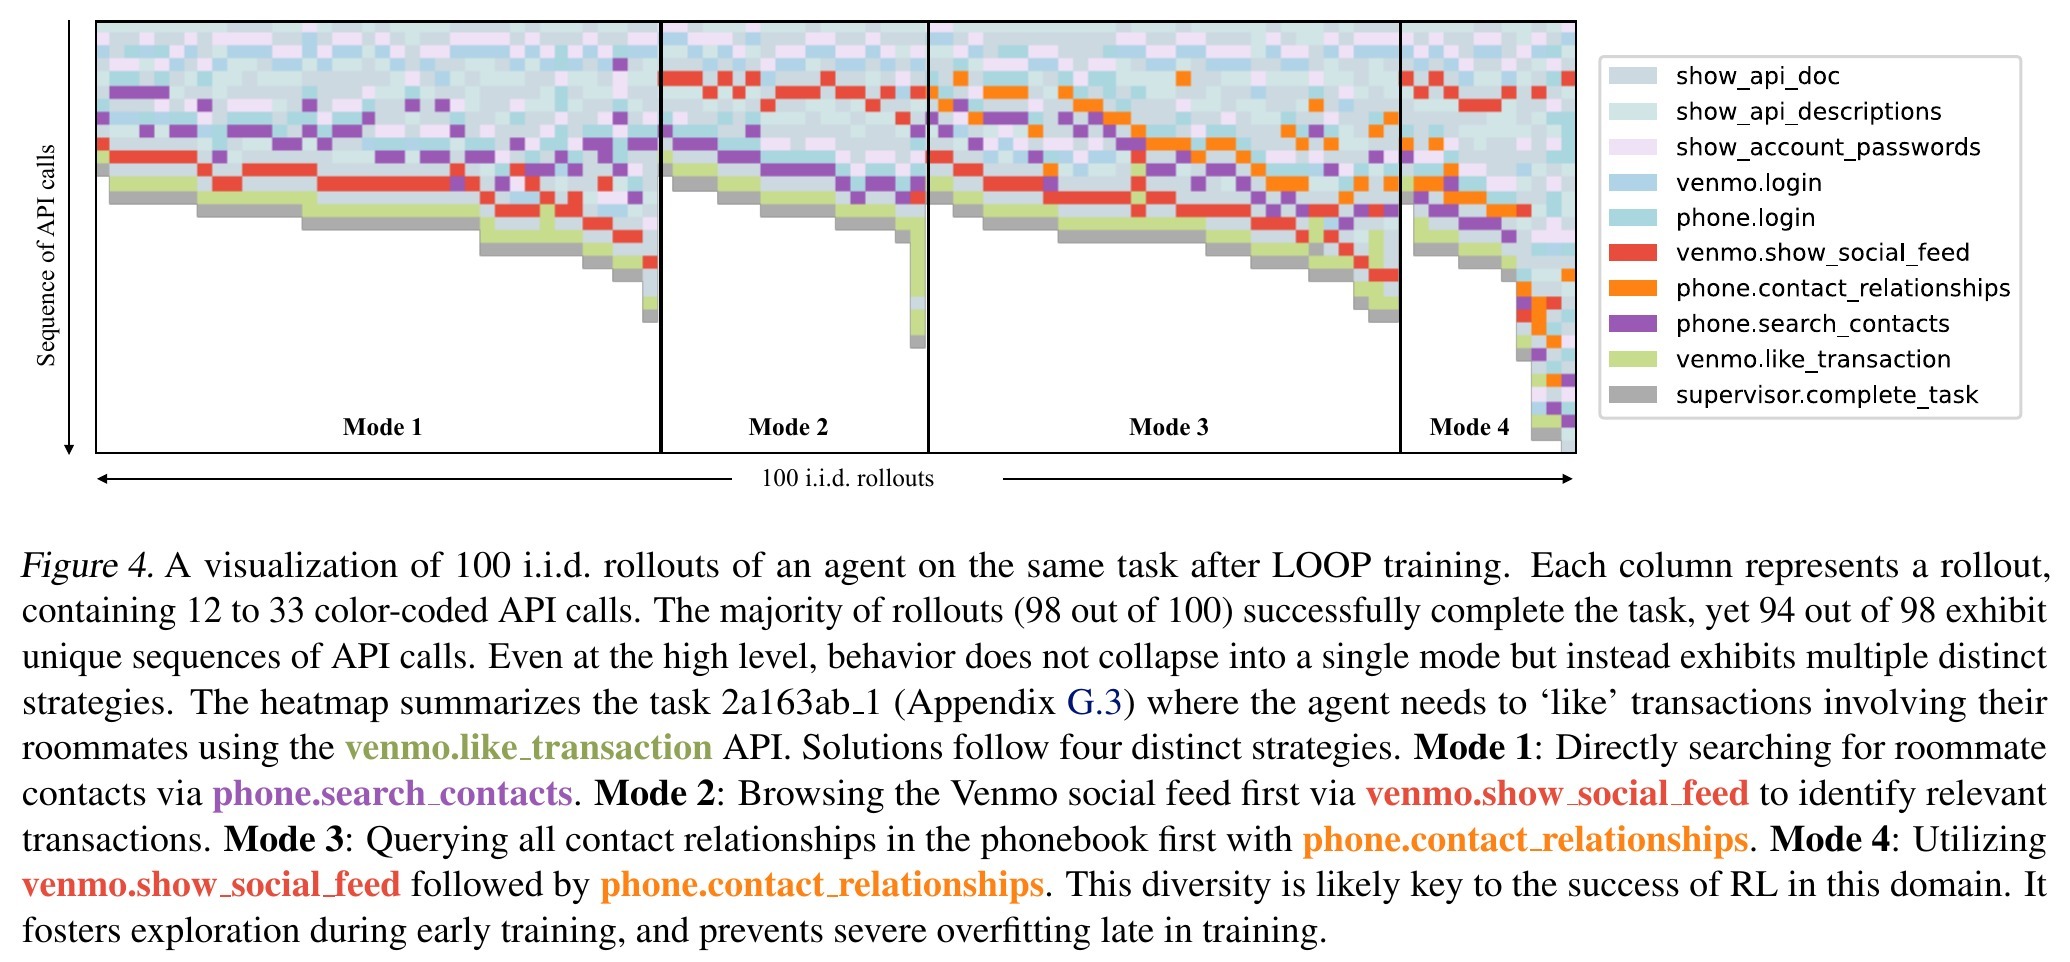
  1. Reinforcement Learning for Long-Horizon Interactive LLM Agents
    Reinforcement Learning for Long-Horizon Interactive LLM Agents. K Chen*, M Cusumano-Towner*, B Huval*, A Petrenko*, J Hamburger, V Koltun, P Krähenbühl. arXiv preprint, 2025.
    RL for long-horizon, multi-turn, tool-using LLM agents. A 32B Qwen2.5 LoRA fine-tune reached 71% on AppWorld, 9 points above OpenAI o1, after training on just 24 scenarios.
  2. Robust Autonomy Emerges from Self-Play
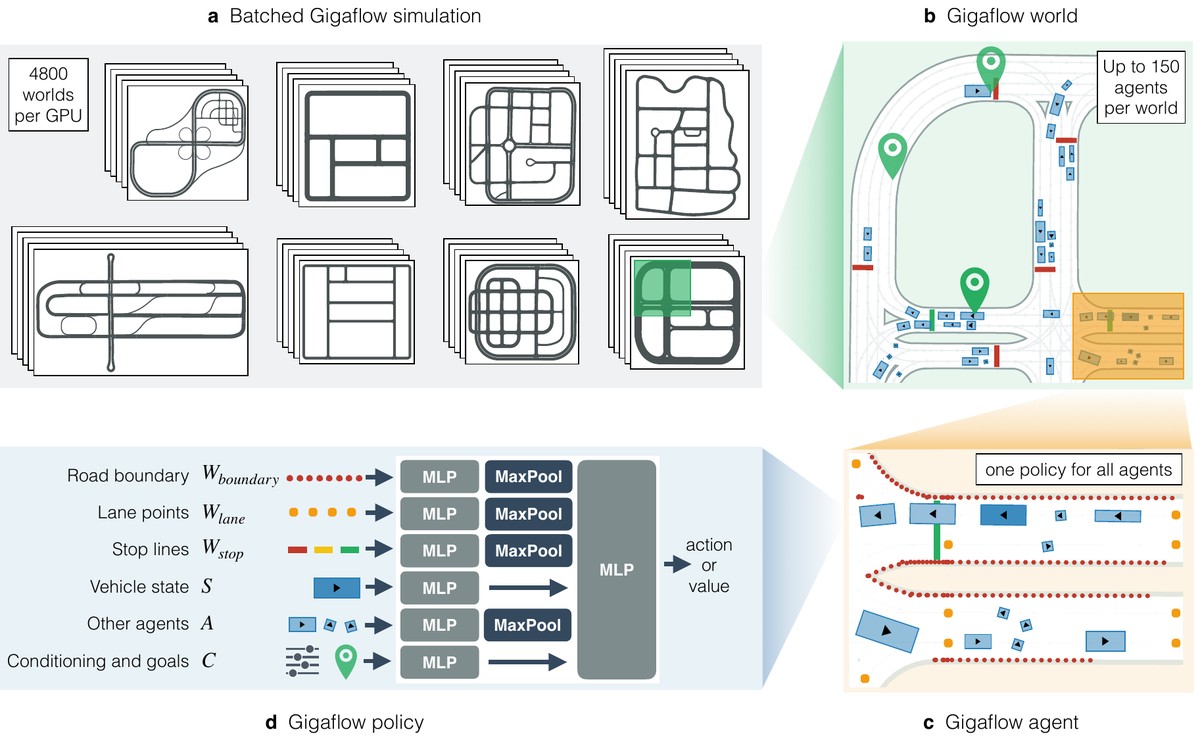
    Robust Autonomy Emerges from Self-Play. M Cusumano-Towner*, D Hafner*, A Hertzberg*, B Huval*, A Petrenko*, E Vinitsky*, E Wijmans*, T Killian, S Bowers, O Sener, P Krähenbühl, V Koltun. In ICML 2025.
    Gigaflow, a batched driving simulator that trains on 42 years of driving experience per hour on a single 8-GPU node: robust and naturalistic driving emerges from 1.6 billion km of self-play, without ever seeing human data.

2024
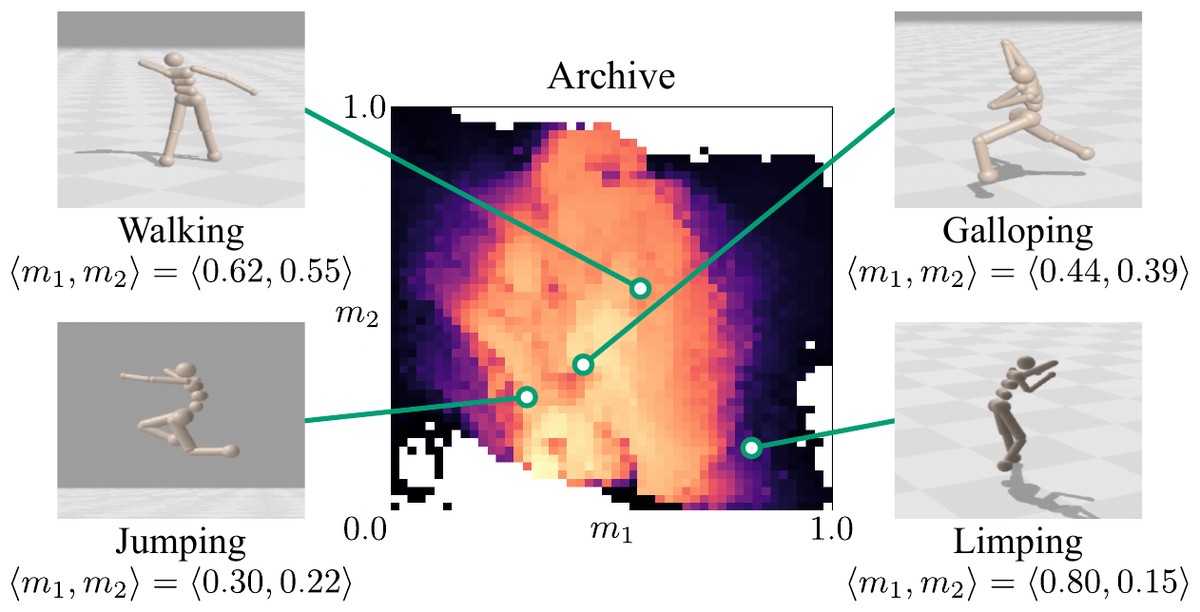
  1. Proximal Policy Gradient Arborescence for Quality Diversity Reinforcement Learning
    Proximal Policy Gradient Arborescence for Quality Diversity Reinforcement Learning. S Batra, B Tjanaka, M Fontaine, A Petrenko, S Nikolaidis, G Sukhatme. In ICLR 2024 (spotlight).
    Combining differentiable quality-diversity search with on-policy RL to train collections of high-performing and behaviorally diverse locomotion policies.

2023

  1. QuadSwarm: A Modular Multi-Quadrotor Simulator for Deep Reinforcement Learning with Direct Thrust Control
    QuadSwarm: A Modular Multi-Quadrotor Simulator for Deep Reinforcement Learning with Direct Thrust Control. Z Huang, S Batra, T Chen, R Krupani, T Kumar, A Molchanov, A Petrenko, J Preiss, Z Yang, G Sukhatme. In ICRA 2023 Workshop on the Role of Robotics Simulators for UAVs.
    A fast modular multi-quadrotor simulator with direct thrust control and domain randomization for sim-to-real reinforcement learning.
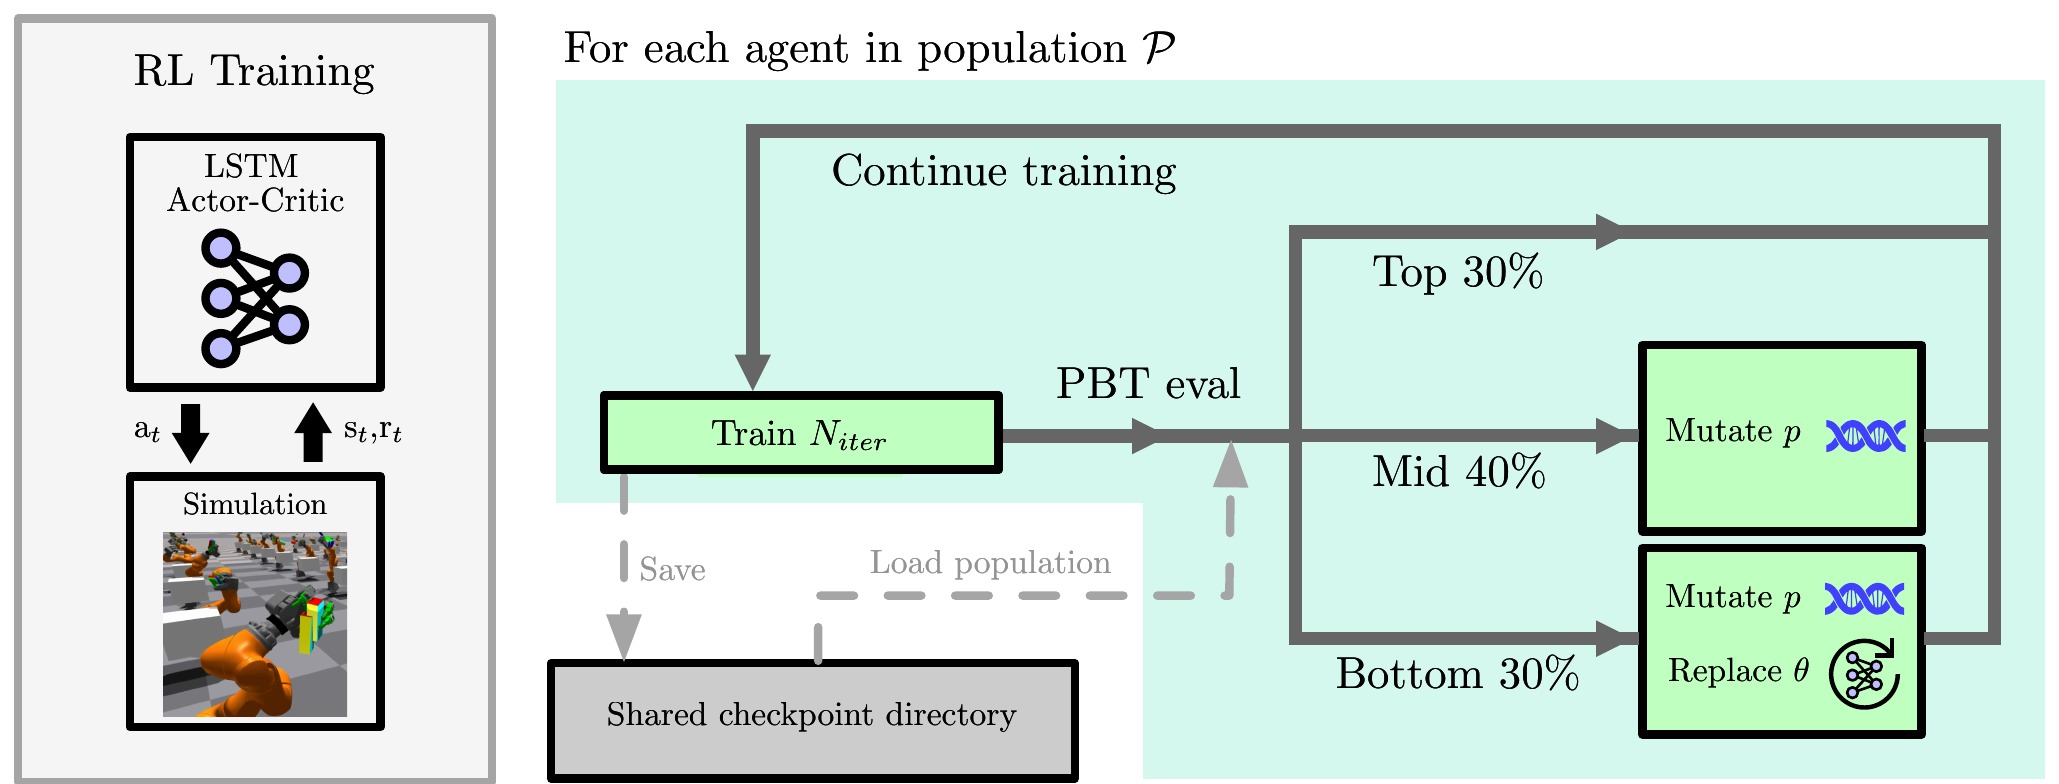
  2. DexPBT: Scaling up Dexterous Manipulation for Hand-Arm Systems with Population Based Training
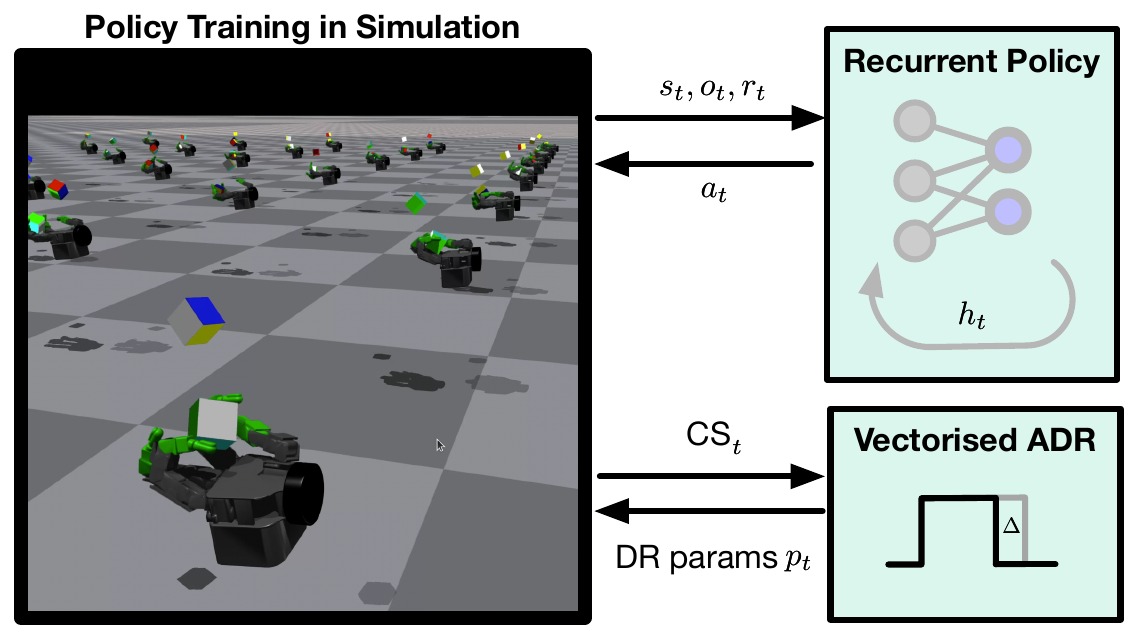
    DexPBT: Scaling up Dexterous Manipulation for Hand-Arm Systems with Population Based Training. A Petrenko, A Allshire, G State, A Handa, V Makoviychuk. In RSS 2023.
    Large-scale reinforcement learning for high-DoF hand-arm systems.
  3. DeXtreme: Transfer of Agile In-hand Manipulation from Simulation to Reality
    DeXtreme: Transfer of Agile In-hand Manipulation from Simulation to Reality. A Handa*, A Allshire*, V Makoviychuk*, A Petrenko*, R Singh*, J Liu*, D Makoviichuk, K Van Wyk, A Zhurkevich, B Sundaralingam, Y Narang, J Lafleche, D Fox, G State. In ICRA 2023.
    Learning dexterous in-hand manipulation in vectorized simulation and deploying policies on the real robot.

2021

  1. Megaverse: Simulating Embodied Agents at One Million Experiences per Second
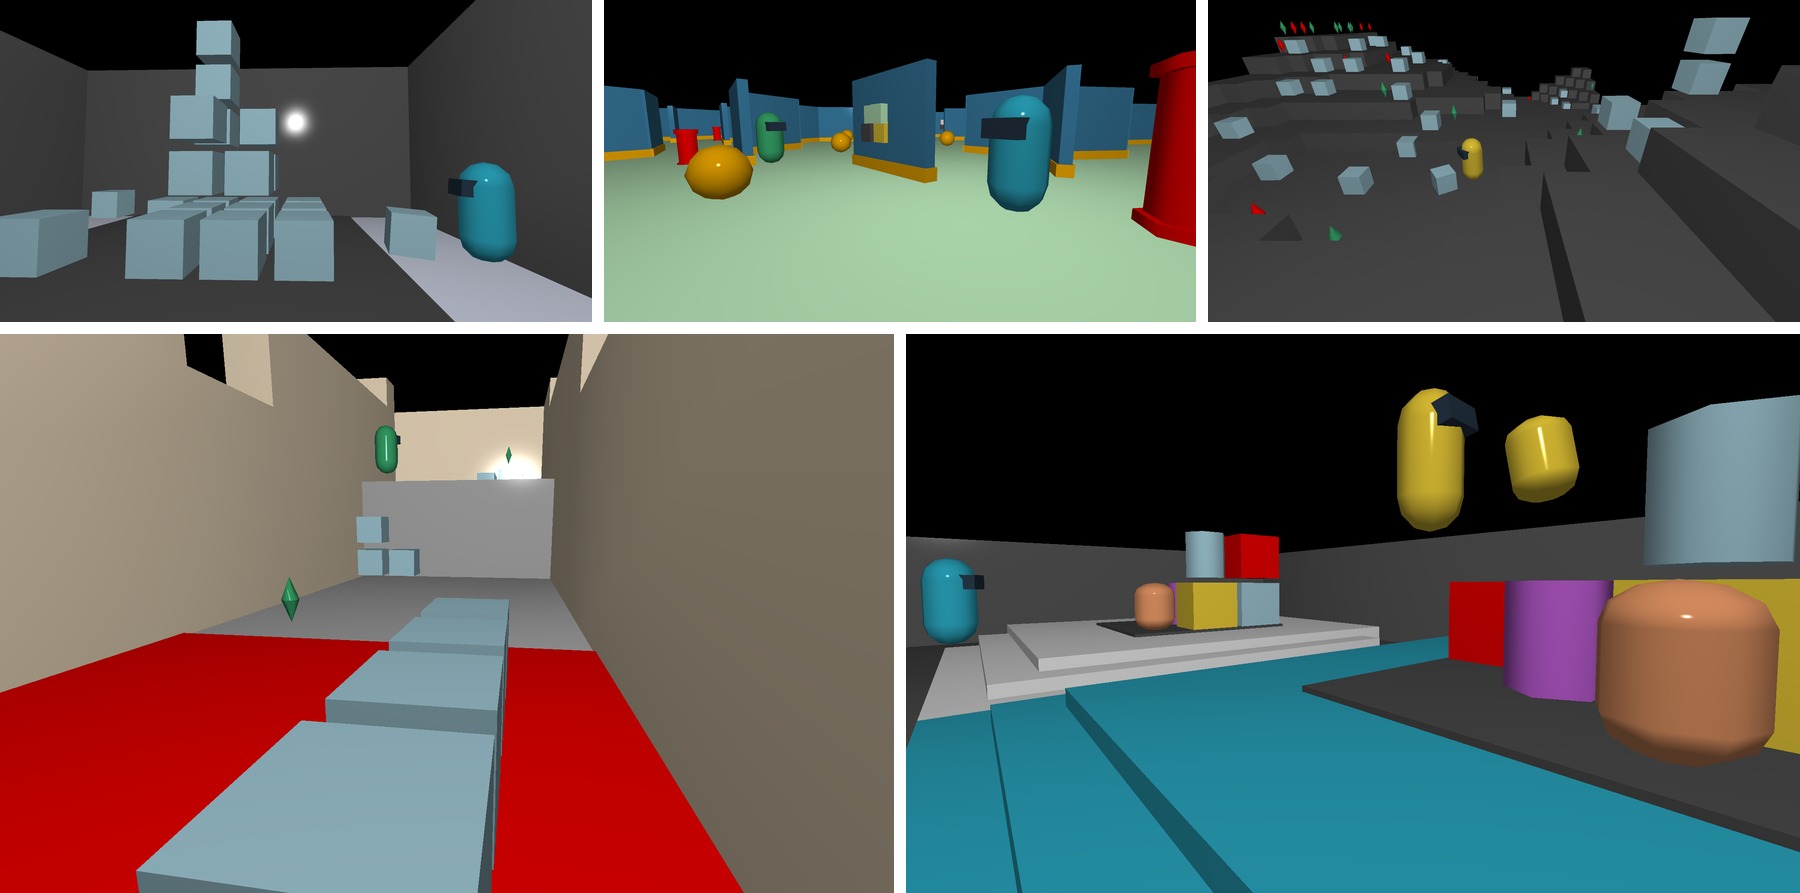
    Megaverse: Simulating Embodied Agents at One Million Experiences per Second. A Petrenko, E Wijmans, B Shacklett, V Koltun. In ICML 2021.
    The fastest (at the time of release) embodied simulator for AI research. 1,000,000+ FPS of immersive experience on a single machine.
    Megaverse: Simulating Embodied Agents at One Million Experiences per SecondMegaverse: Simulating Embodied Agents at One Million Experiences per Second
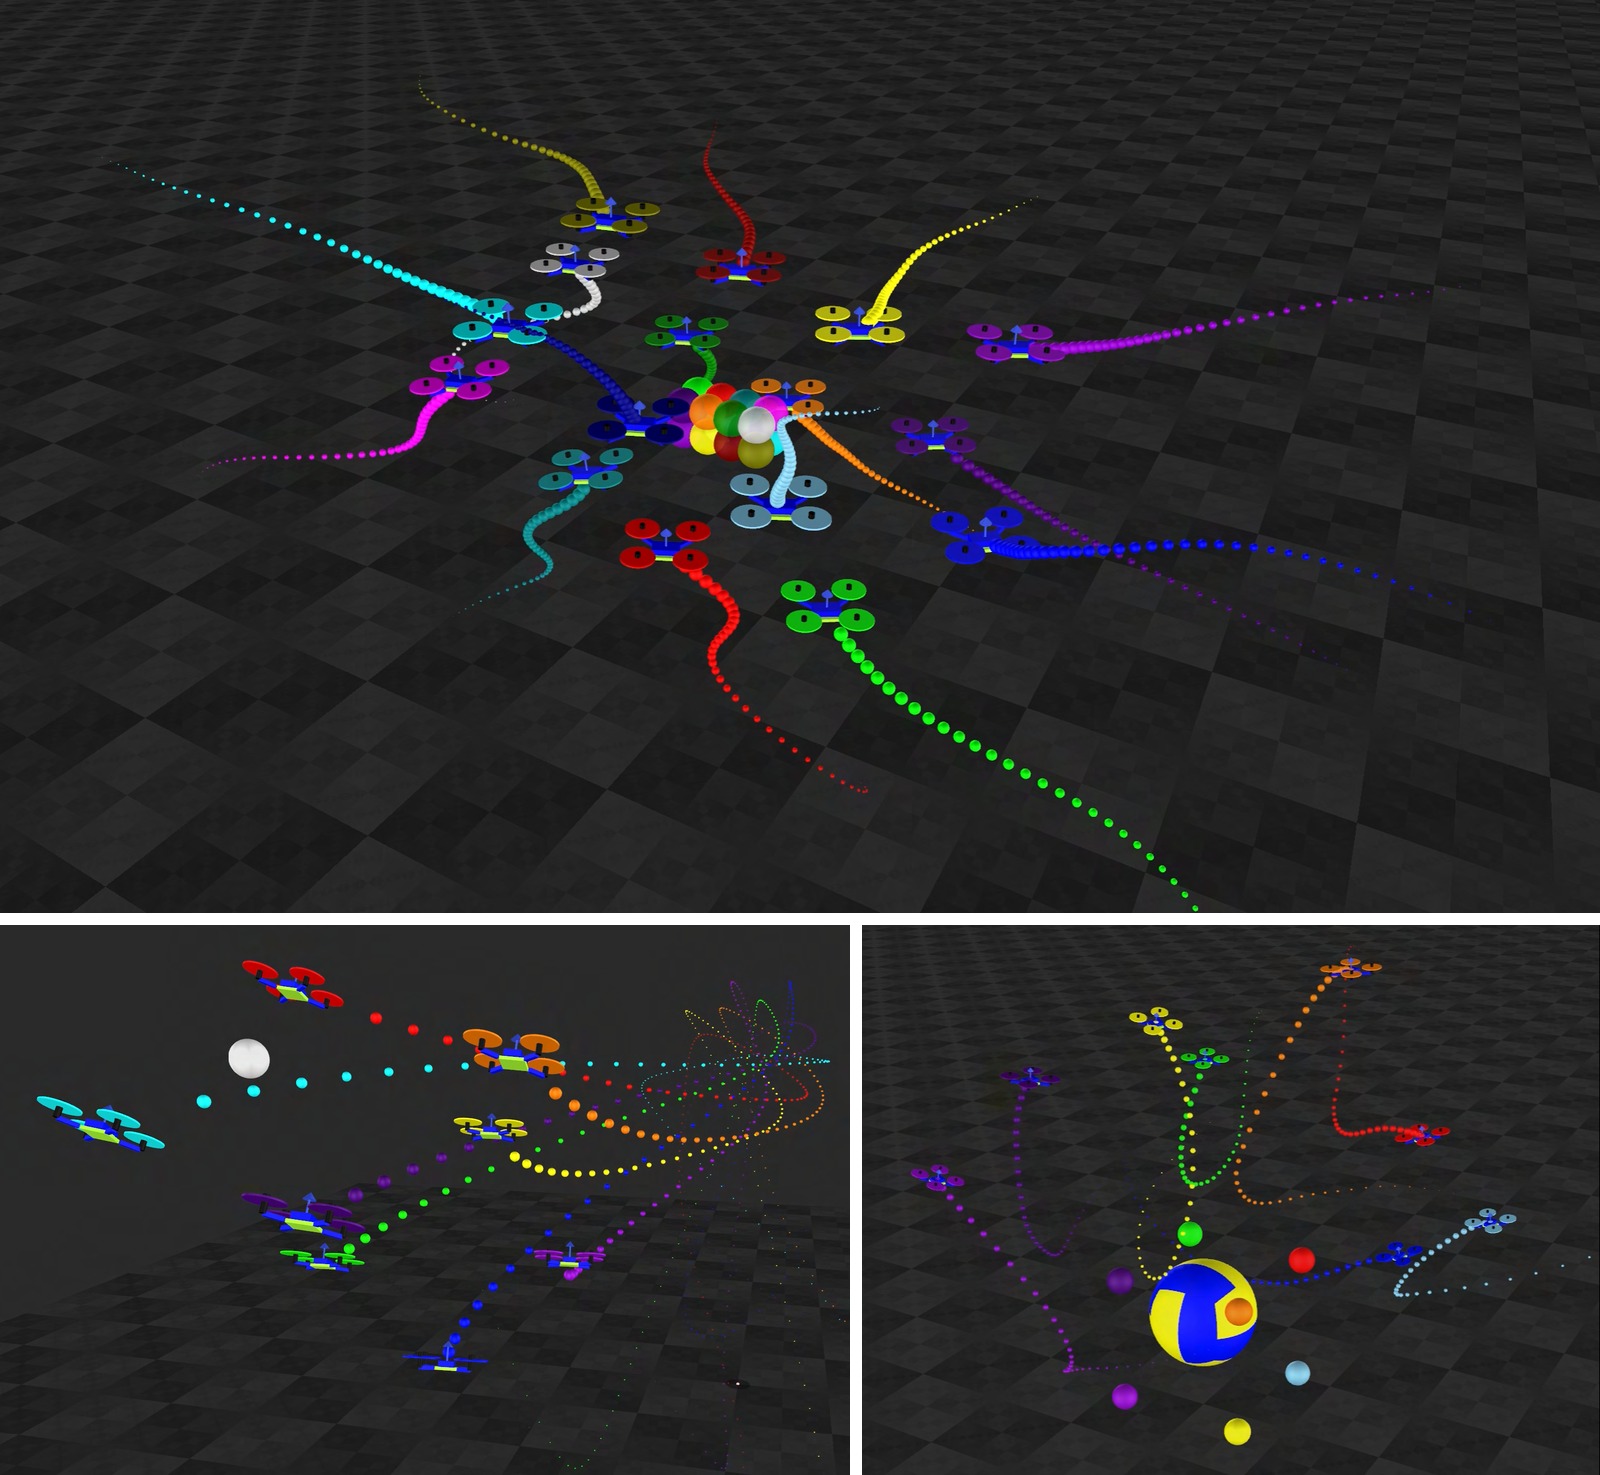
  2. Decentralized Control of Quadrotor Swarms with End-to-end Deep Reinforcement Learning
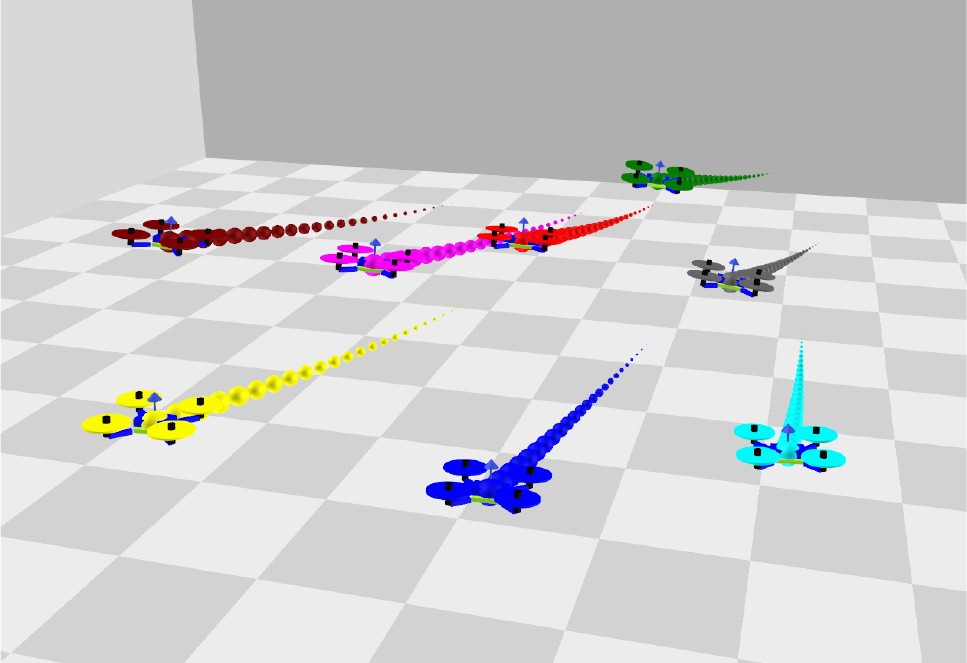
    Decentralized Control of Quadrotor Swarms with End-to-end Deep Reinforcement Learning. S Batra*, Z Huang*, A Petrenko*, T Kumar, A Molchanov, G Sukhatme. In CoRL 2021.
    End-to-end learning of neural policies for quadrotor swarms with sim-to-real transfer.
    Decentralized Control of Quadrotor Swarms with End-to-end Deep Reinforcement LearningDecentralized Control of Quadrotor Swarms with End-to-end Deep Reinforcement Learning
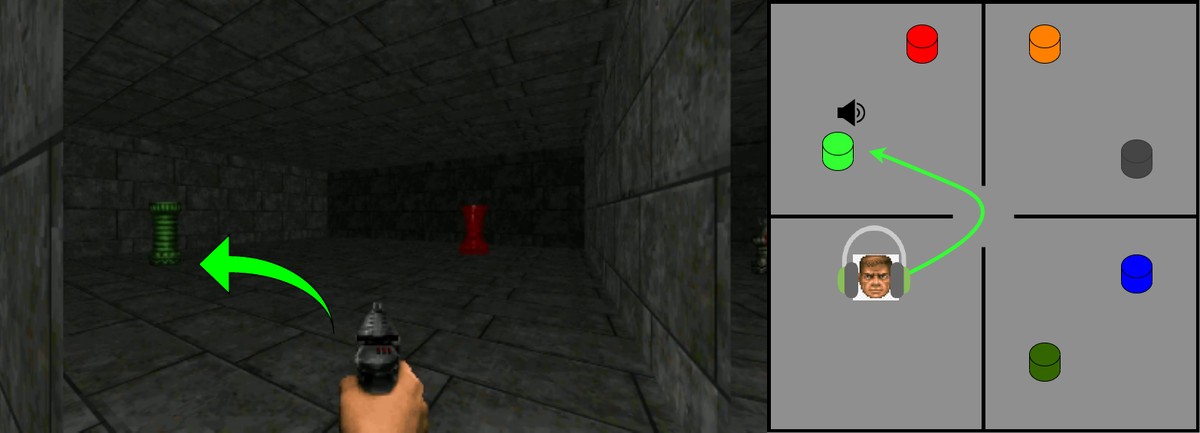
  3. Agents that Listen: High-Throughput Reinforcement Learning with Multiple Sensory Systems
    Agents that Listen: High-Throughput Reinforcement Learning with Multiple Sensory Systems. S Hegde, A Kanervisto, A Petrenko. In IEEE Conference on Games, 2021.
    Adds sound to ViZDoom and shows that high-throughput RL agents learn to use audio cues alongside vision.
  4. Large Batch Simulation for Deep Reinforcement Learning
    Large Batch Simulation for Deep Reinforcement Learning. B Shacklett, E Wijmans, A Petrenko, M Savva, D Batra, V Koltun, K Fatahalian. In ICLR 2021.
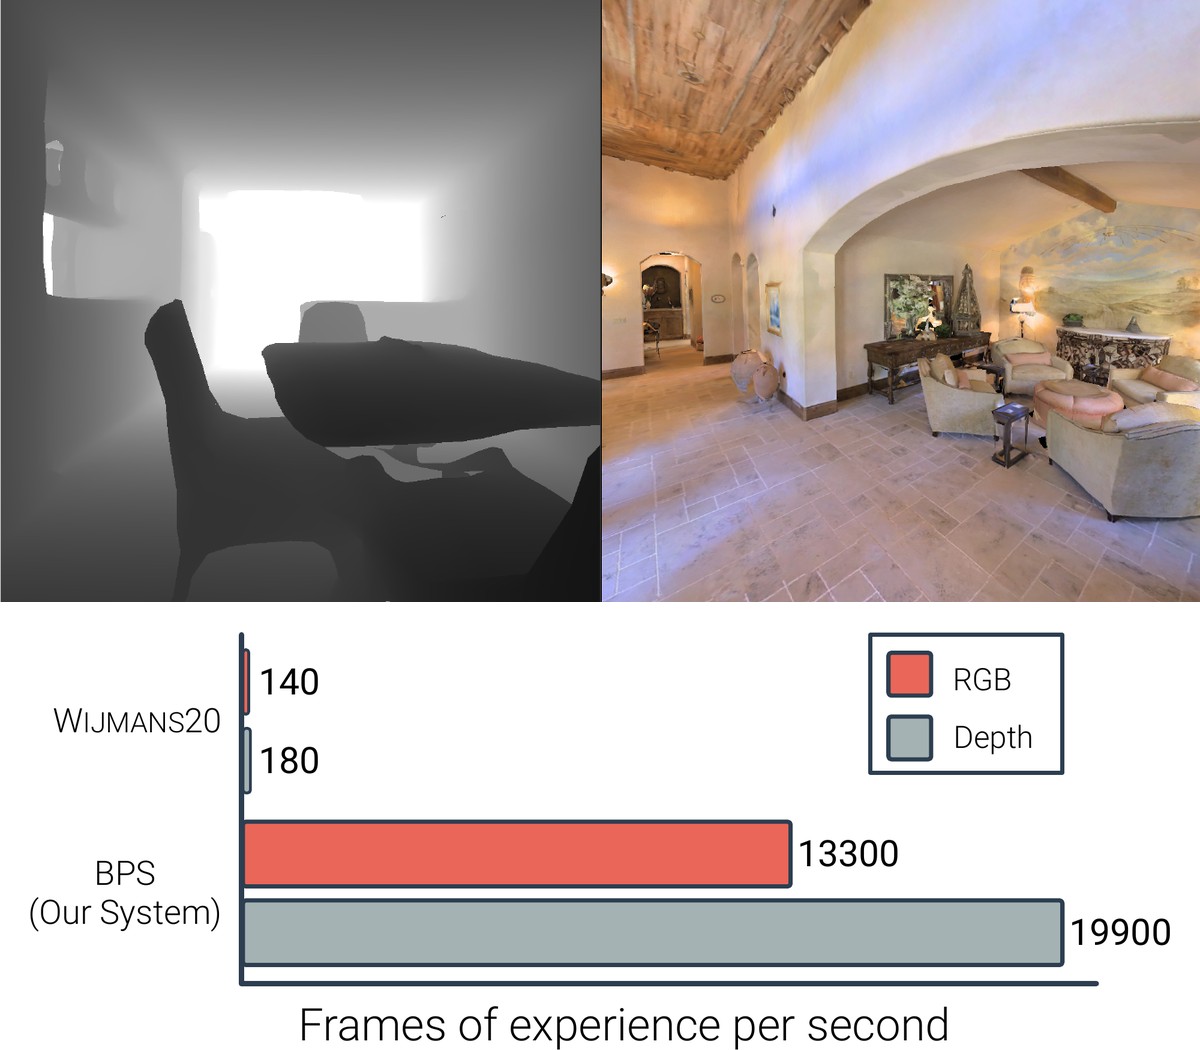
    Batched simulation and rendering train PointGoal navigation agents at 19,000+ FPS on a single GPU, two orders of magnitude faster than prior work.

2020

  1. Sample Factory: Egocentric 3D Control from Pixels at 100000 FPS with Asynchronous Reinforcement Learning
    Sample Factory: Egocentric 3D Control from Pixels at 100000 FPS with Asynchronous Reinforcement Learning. A Petrenko, Z Huang, T Kumar, G Sukhatme, V Koltun. In ICML 2020.
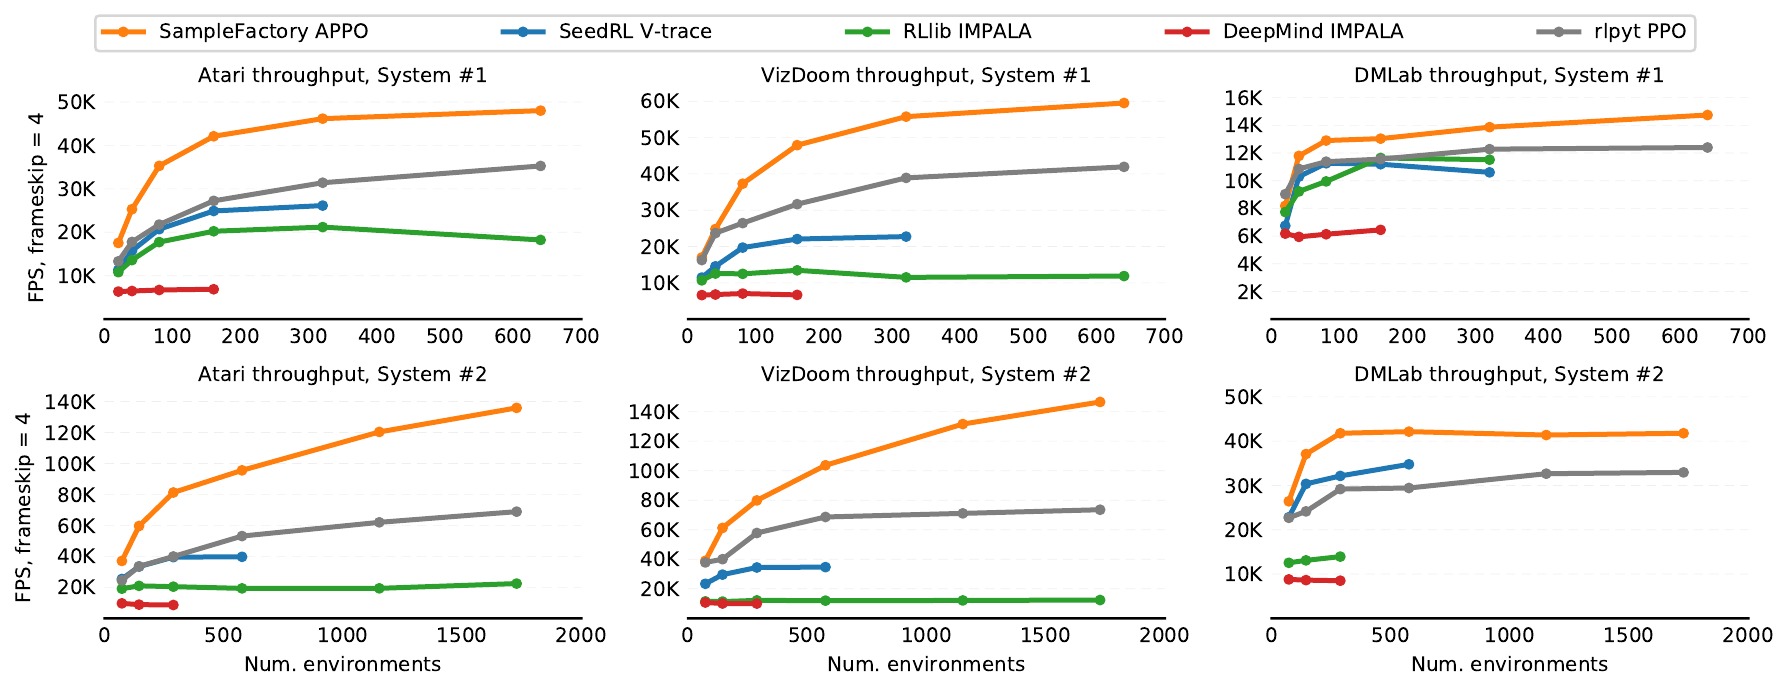
    Reinforcement learning framework with the highest single-machine training throughput at the time of publication, about 10x faster than traditional synchronous RL implementations. SOTA results in challenging VizDoom and DMLab environments.
    Sample Factory: Egocentric 3D Control from Pixels at 100000 FPS with Asynchronous Reinforcement LearningSample Factory: Egocentric 3D Control from Pixels at 100000 FPS with Asynchronous Reinforcement Learning